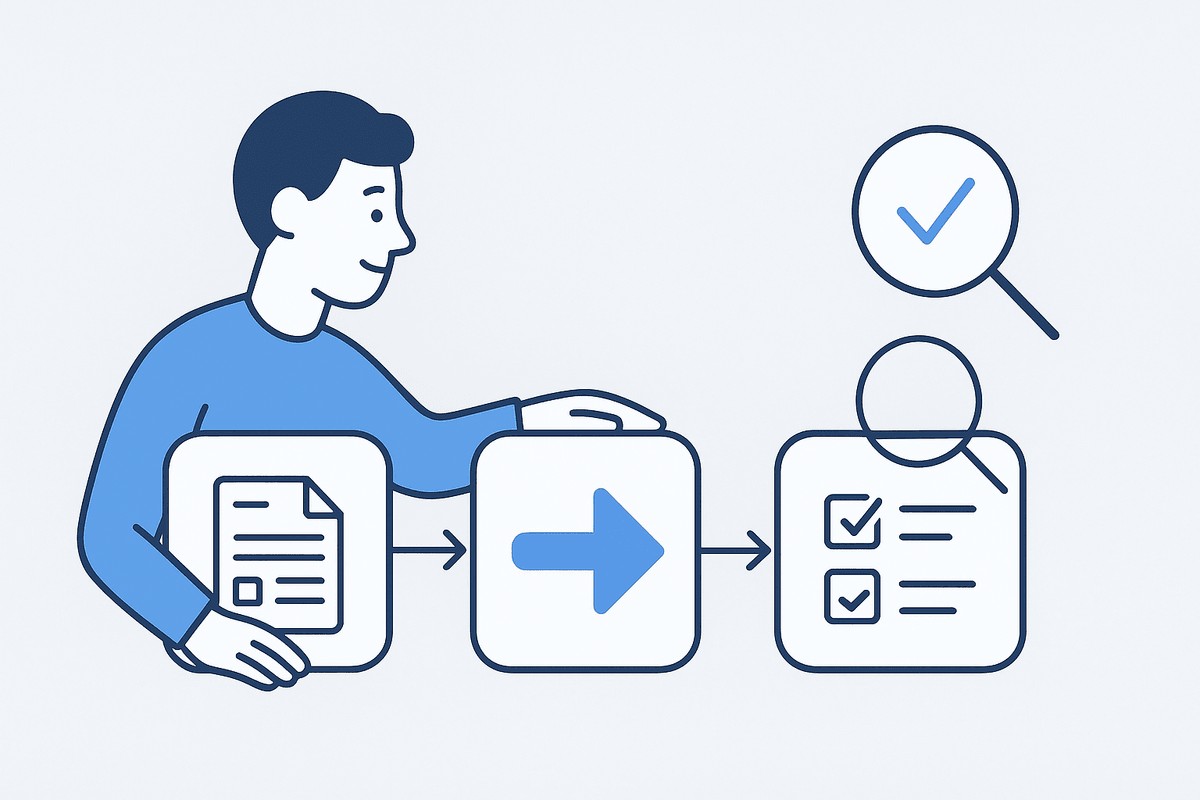
The P-E-V prompt workflow for better LLM output quality
Put your judgment criteria in the prompt and the results change
The P-E-V workflow is a prompt pattern that gives an LLM a validation checklist in three steps. How it differs from CoT and ReAct, and fixing vague input.
P-E-V (Plan-Execute-Validate) is a prompt design pattern that doesn't just tell an LLM "what to do" but also gives it "how to judge and how to check itself." It's a three-step structure (plan, execute, validate), and the key is that instead of asking for an answer right away, you set up a judgment checklist first.
Why P-E-V is needed
Ask an AI to "write questions people would actually search for with this keyword," and you'll often get results like this.
> What are the core features and benefits of Service X?
Would a person really search like that? The most common mistake in prompt engineering is saying only "what to do" and leaving out "how to judge." LLMs follow instructions faithfully, but without judgment criteria they tend to retreat to the safest choice, meaning the vaguest and broadest category.
How it differs from CoT and ReAct
| Pattern | Core idea | Difference |
|---|---|---|
| CoT (Chain-of-Thought) | "Think step by step" | Shows the reasoning but has no validation step before output[1] |
| ReAct | "Observe and act" | Focused on external tool calls and an observe-act loop[2] |
| P-E-V | "Plan → execute → validate" | The key is a self-check (Validate) step right before output |
If CoT is a pattern that creates a "flow of thought," P-E-V is closer to a "checklist for thought." It's a structure that makes the LLM double-check "is this right?" before it answers. Google's prompt design guide also points in the direction that the more concretely you give a model its role and judgment criteria, the more stable its output quality[3].
The three steps of the P-E-V workflow
The P-E-V workflow runs in three steps: plan finds intent signals in the input, execute picks a category from those signals and generates the result, and validate self-checks the output against a checklist before it goes out.
Plan      → Find intent signals in the input
            "price" → qualify, "vs" → compare, "how to" → action

Execute   → Choose a category based on the signals and generate the result
            If the signals are vague, follow a predefined default

Validate  → Self-check against a checklist before output
            "Does this category really fit this signal?"
            "Did I follow the constraints (tone, length, repeated phrasing)?"
Three patterns for when an LLM classifies vague input into the wrong category
When an LLM classifies vague input into the wrong category, three patterns help: a decision tree that makes signals explicit, a validation checklist that filters before output, and tone rules written as explicit constraints.
1. Make signals explicit with a decision tree
Just telling an LLM to "classify this" isn't enough. You have to tell it explicitly, "if you see this signal, it's this category."
Example of signal-based routing:
├─ "price", "cost", "fee", "plan"             → qualify
├─ "vs", "compare", "alternative", "instead"  → compare
├─ "how", "how to", "set up"                  → action
├─ "not working", "error", "problem"          → solve
├─ "review", "recommend", "best"              → recommend
├─ "what is", "what", "concept"               → concept
└─ Vague cases                                → default
In practice, the most important decision here is the default. If you set the default for vague cases to the broadest category (for example, concept explanation), results keep skewing toward that category. In reality, when people ask about a brand, it's common for many of their questions to be closer to "Is this any good?" or "Can I use this?" than "What is this?" Simply changing the default to match real usage patterns can shift the distribution significantly.
2. Add a second line of defense with a validation checklist
After the LLM generates a result, have it check itself before output.
| # | Check item | Action on failure |
|---|---|---|
| 1 | There's a price or cost signal; is the current classification right? | Reclassify |
| 2 | There's a comparison expression ("vs," "alternative"); is the current classification right? | Reclassify |
| 3 | There's an action verb ("set up," "create"); is the current classification right? | Reclassify |
| 4 | Did it follow the tone rules (repeated endings, length)? | Fix the tone |
| 5 | Is the same sentence ending repeated 3 or more times? | Change the ending |
This checklist catches, as a second pass, misclassifications missed at the decision tree step. With only Plan and Execute, it's effectively not very different from CoT. Validate is the key differentiator that sets P-E-V apart.
3. Put tone rules in as explicit constraints
Tone wavers too if you leave it to the model's judgment. For Korean, results stabilize only when you explicitly add rules such as "use the polite haeyo style throughout, limit to 20-50 characters, never use the same sentence ending three times in a row." For English, you'd add rules like a word count range and a preference for conversational phrasing.
Management structure: consolidate into a single source of truth
Scattering P-E-V logic across many files makes it hard to manage. Consolidating it into one prompt module (a single source of truth, or SSOT) is better for maintenance.
| Item | Distributed management | SSOT consolidation |
|---|---|---|
| When changes are needed | Edit several files one by one | Edit just 1 file |
| Risk of inconsistency | High (managed independently) | Low |
| Test scope | Each piece needs its own test | Testing 1 place confirms it everywhere |
What we learned
When you apply this pattern to several content and classification pipelines, a few things show up consistently.
P-E-V is a prompt pattern, not a model, so it isn't tied to a model. The core is the structure of putting a decision tree and a validation checklist into the prompt, so if you port the same structure to GPT, Gemini, or Claude models, similar improvements appear.
The default setting has the biggest effect on balancing the distribution. Models tend to retreat to the broadest category on vague input, so simply changing the default to something closer to real usage patterns often eases the skew considerably. This is where the smallest change has the biggest effect.
A decision tree without a validation checklist isn't enough. The decision tree handles first-pass classification, but edge cases (for example, whether "price comparison" is qualify or compare) can only be caught at the validation step. With only Plan and Execute, it's no different from CoT, and the fact that Validate is the key differentiator of P-E-V is confirmed again and again in practice.
In a content pipeline, the quality of the questions, classifications, and categories AI produces ultimately ties directly to which prompts you target in AI search. The habit of explicitly designing judgment criteria and validation procedures, as P-E-V does, also becomes the foundation for creating accurate, structured content that AI is likely to cite.
For related reading, see RAG hallucination defense strategies: classify the types and know the limits of automated validation, Five agentic workflow patterns: from prompt chaining to orchestrators, and A location page checklist for clinics and academies: what to include to get cited in AI search.
Frequently asked questions
Does P-E-V only work with specific models?
No. P-E-V is a pattern for structuring prompts, not a model. Because it works by putting a decision tree and a validation checklist into the prompt, you can apply the same structure to GPT, Gemini, or Claude models.
Why isn't chain-of-thought enough on its own?
CoT nudges the model to think step by step, but it has no step where the model checks its own result before output. P-E-V adds a Validate step so the model double-checks whether the generated result actually matches the rules it set at the start.
How do I design a validation checklist?
Start with a list of questions asking whether the signal and the category actually match. For example, turn a question like "Price was mentioned, so is this category right?" into a checklist item and instruct the model to reclassify if it fails. As your classification criteria grow, expand the checklist with them.
References
Summary
- P-E-V (Plan-Execute-Validate) is a prompt design pattern that doesn't just say "give me the answer" but supplies judgment criteria and a validation procedure along with it.
- LLMs tend to retreat to the safest, broadest category on vague input, so a single default setting has a big effect on the distribution of results.
- A decision tree alone can't catch edge cases. The validation checklist, a self-check step before output, is what sets P-E-V apart.
- The pattern isn't tied to a model, so you can port the same structure to GPT, Gemini, or Claude.
Produce the content this post covers from your brand standard
TRAIL Studio registers the brand standard once and produces cardnews, detail pages, product photos, shorts and blog posts from it. Generated output is reviewed and edited by a person before it ships.
More posts
Best AI Search Optimization Tools 2026: 6 GEO Tools Ranked
We compared six tools that check whether ChatGPT and other AI answers mention your brand, on measurement, action, engines, Korea support, and price.
Why Does ChatGPT Cite Listicles? Format vs. Hierarchy
Listicles split items cleanly, so AI can extract just what it needs. How to write citable listicles, whether format alone is enough, and how to build hierarchy.
What is GEO? Which pages to start with, and in what order
GEO structures content so generative search like ChatGPT and AI Overviews cites it. Does it replace SEO, what order to run it in, and how to measure it.
Keep reading on this topic
- Topical authority: why pillar-cluster beats a single postTopical authority comes from content clusters, not single posts: the pillar-cluster model, how to design one, why it wins in AI search, and when it's enough.
- A 4-step framework for SEO and GEO: split teams or merge?SEO and GEO work best on one content quality foundation. Whether to split or merge teams, a 4-step framework, why unified plans fail, and one shared metric.
- SEO and GEO top spots: high rankings, missing in AI answersReaching the top now covers how AI answers mention you, not just rankings. What changed, how to manage both tops, and why competitor comparison matters.
This post is part of the Content category, which collects all 41 posts on the topic. See all posts in Content