How AI search picks which page to cite: four gatekeepers
A controlled study across 6 models and 252,000 trials on what decides a citation when two similar pages compete
When two similar pages compete for one AI-search answer, four signals decide the citation: topic match, price, recent date, and front position. A Sprinklr team pitted two documents that differ in exactly one factor against each other across 6 AI models and 252,000 trials, isolating what decides a citation under controlled conditions.
When AI search picks one of two similar pages, four signals filter first: topic match, a stated price, a recent timestamp, and a front position in context, and dropping any one sharply raises the odds of losing the citation to the rival page. A Sprinklr team ran 252,000 trials across 6 AI models, pitting two documents that differ in exactly one content factor against each other, and reads these four as necessary conditions [1]. Once the gatekeepers are met, second-tier factors like specs and evidence made the difference (odds ratios of 2.1 to 243 by the authors' summary, a few reaching over 10,000 in some models), while paragraph formatting was almost unrelated to being cited [1].
This article reads the body and tables of the paper posted on arXiv and checks the figures against it. All numbers are the paper's experimental results, and since the paper publishes no code or data link, we have not reproduced them [1]. The study fixes the contest to two candidates so it can isolate one factor at a time, which differs from real AI search handling many pages at once [1]. We also build an AI-search diagnostic tool, so the part about our product is in the last section.
Why run the experiment as a contest?
Data collected from live services makes it hard to tell which content factor caused a citation, because the content effect is tangled with retrieval rank, presentation order, and interface artifacts [1]. Earlier GEO work measured the visibility of a single page within a fixed result set, but did not directly measure which of two similar candidates wins when they go head to head [2].
So the authors designed a controlled test that places only two documents in the answer context [1]. Each pair differs in one factor while facts, price, specs, and length are held equal, and brands, model names, and publishers are replaced with fictional aliases so that pretraining familiarity cannot leak in [1]. Bias from presentation order is canceled by swapping the order of the two documents [1].
The scale is 6 models (Gemini-2.5-Flash, Claude-3.5-Sonnet, Kimi-K2, and three GPT models), 18 content factors, and 252,000 trials [1]. Each factor's effect on citation is reported as an odds ratio (OR), where a larger OR means the side with that factor is more likely to be cited in the contest [1].
What does AI search look at when choosing a page to cite?
Four signals acted as gatekeepers [1]. Whether the page covers the same topic as the query (topic match), whether a price is stated (price shown), whether the date is recent (recent timestamp), and whether the page sits near the front of the candidate list (front position) [1]. Front position is set by retrieval and ranking, so it is a candidate-slot order rather than something you edit on the page, and it is different from where text sits inside the page [1]. This position effect lines up with research on positional bias in language models [3].
All six models reacted to these four in the same direction, with odds ratios ranging from single digits (the price factor was around 6x in some models) to over 10,000 [1]. The authors read these four as necessary conditions: drop any one and the odds of losing the citation to a document that changed one factor grow that much [1]. Because factors were tested one at a time, this does not show how they interact when several change together [1].
Price stands out. A page that leaves out the price fell behind at gatekeeper scale [1]. A page that moves the price to a contact-us line is likely to see the same effect, though the paper did not test that specific case [1].
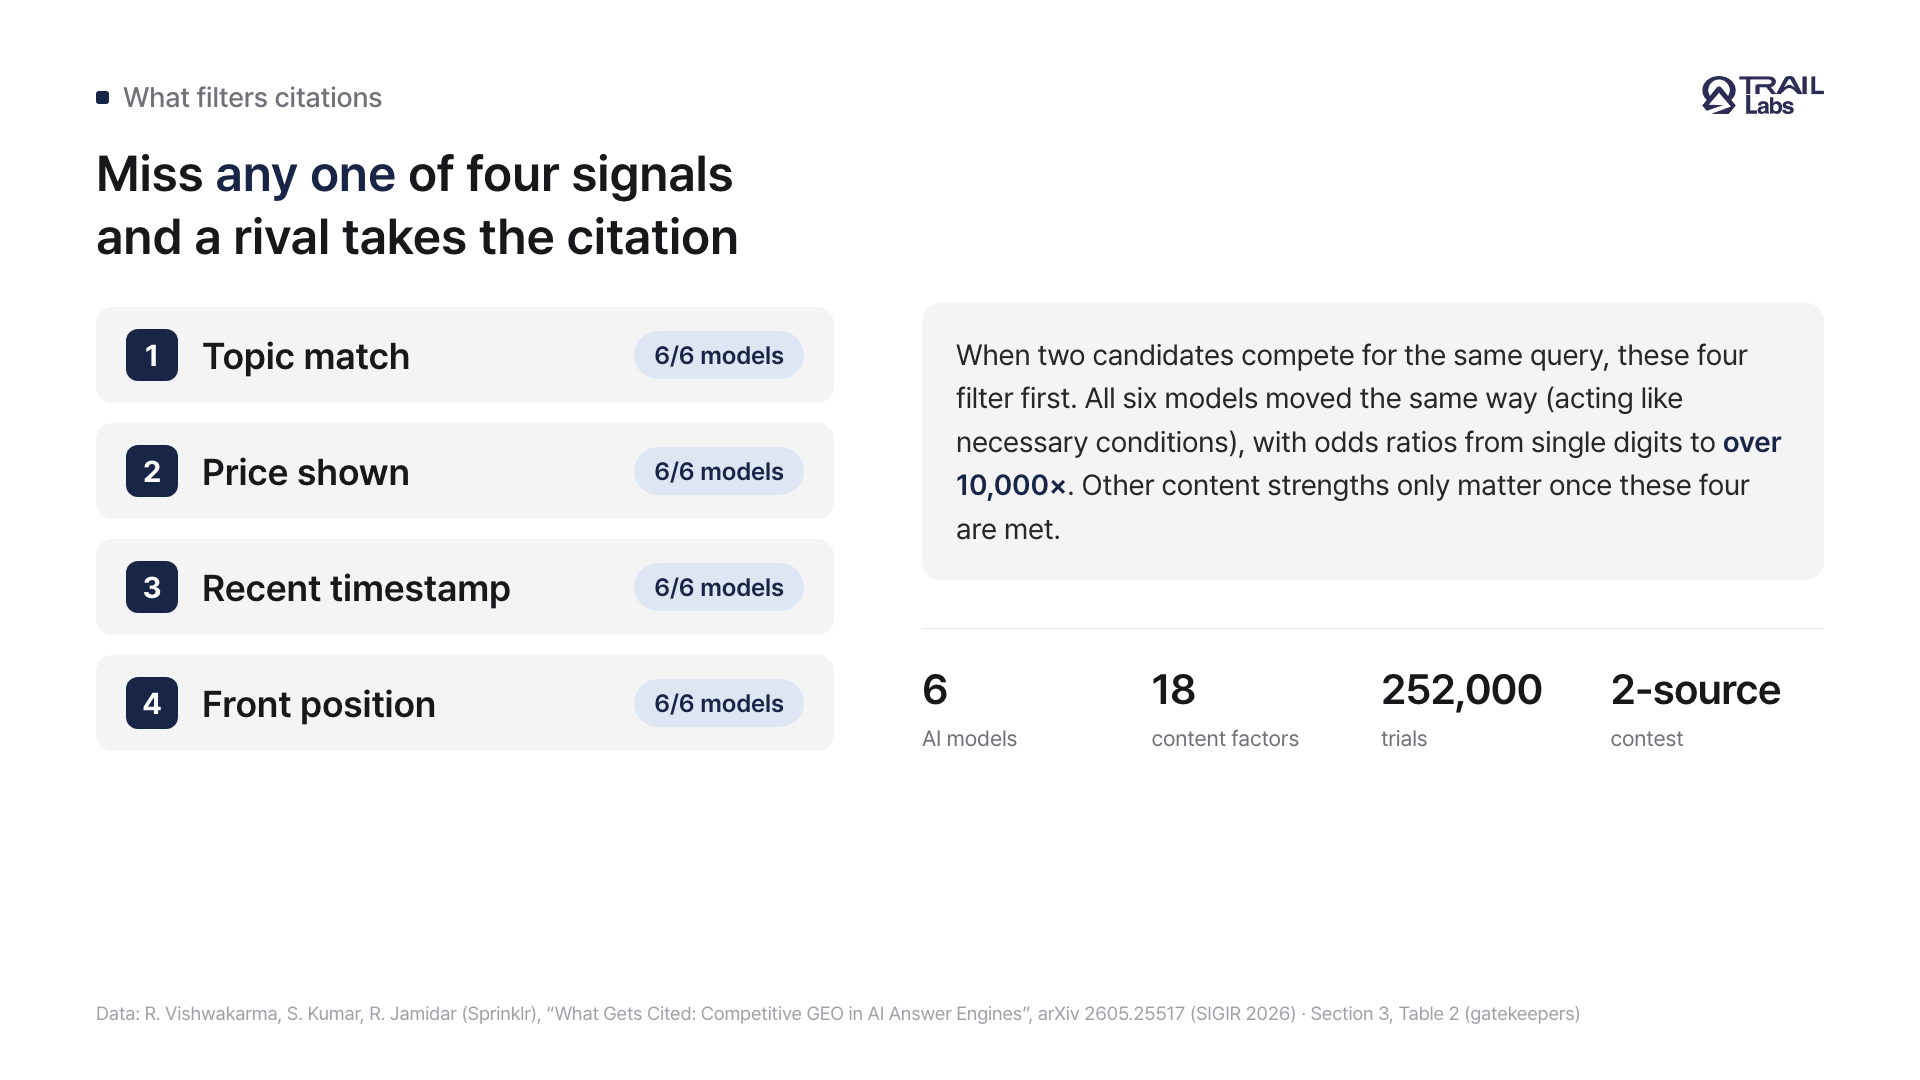
Figure 1. The four gatekeepers that filter citations.
After the gatekeepers, what decides a citation?
Only after the gatekeepers do second-tier factors matter [1]. Completeness such as spec information and competitor comparisons, trustworthiness such as confident tone and evidence, and social proof such as rating and review counts all sit here [1]. By the authors' summary they decided citations with odds ratios from 2.1 to 243, with a few factors reaching over 10,000 in some models [1].
| Second-tier factor | Category | Odds ratio (OR), range across models |
|---|---|---|
| Specs stated | Completeness | 8.6-10,000+ |
| Deep coverage | Competitive standing | 4.0-10,000+ |
| Confident tone | Trustworthiness | 2.7-754 |
| Evidence given | Trustworthiness | 2.1-10,000+ |
| Social proof | Competitive standing | 2.1-10,000+ |
| Query terms present | Topic match | 6.0-40 |
Table 1. Second-tier factors after the gatekeepers and their odds-ratio ranges across models. Values over 10,000 are unstable estimates to be read as direction only [1].
Missing spec information or hedged phrasing ("maybe", "could be") was a sizable loss, while content that carried the key specs and evidence together did better in the contest [1]. The authors' recommended priority is to meet the gatekeepers first, then make low-cost fixes like price, date, and query terms, then differentiate with specs, comparisons, and competitive positioning [1].
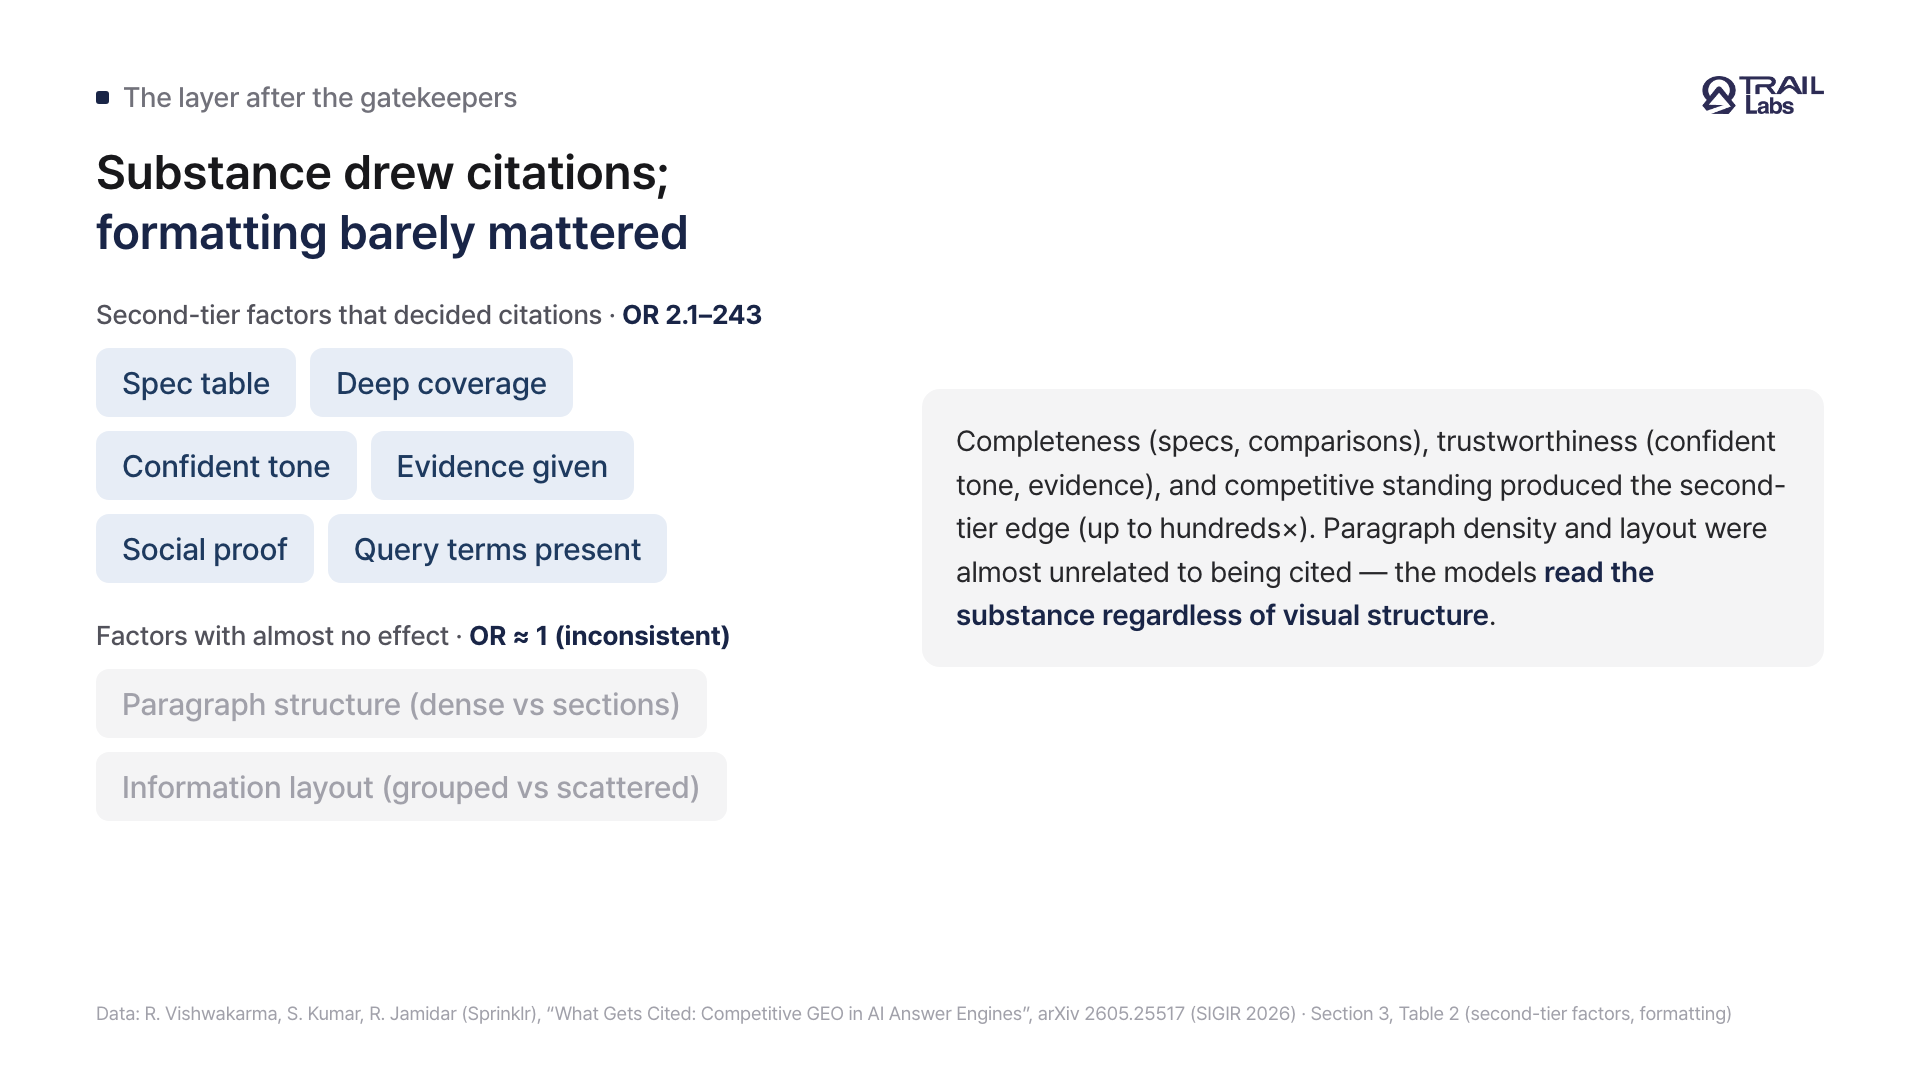
Figure 2. Substance drew citations, while formatting barely mattered.
Do paragraph structure and formatting affect citations?
In this experiment they barely did. Whether paragraphs were dense or split into sections, and whether information was grouped or scattered, had almost no relation to being cited [1]. The authors read this as the models reading the substance regardless of visual structure [1]. So they advise filling in missing information before polishing format [1].
The date results produced a counterintuitive order. A 2026 date helped more than a 2019 one, and a missing date beat an old one [1]. But the no-date-beats-old-date result held only in some models and was small [1]. So rather than read it as a prompt to delete dates, look first at keeping a date current [1].
Do AI engines use different citation criteria?
The number of factors each engine responds to differed [1]. Kimi-K2 reacted to 83% of factors and was the most sensitive, Claude to about half, and Gemini to a third, while the three GPT models were in the middle and behaved similarly, which the authors read as architecture mattering more than model size [1]. Gemini watches few factors, but 67-78% of its significant factors landed at odds ratios over 10,000, a near-binary pattern [1].
Even so, across this experiment's six models the four gatekeepers pointed the same way [1]. That gives a reason to check these four before worrying about differences between engines [1].
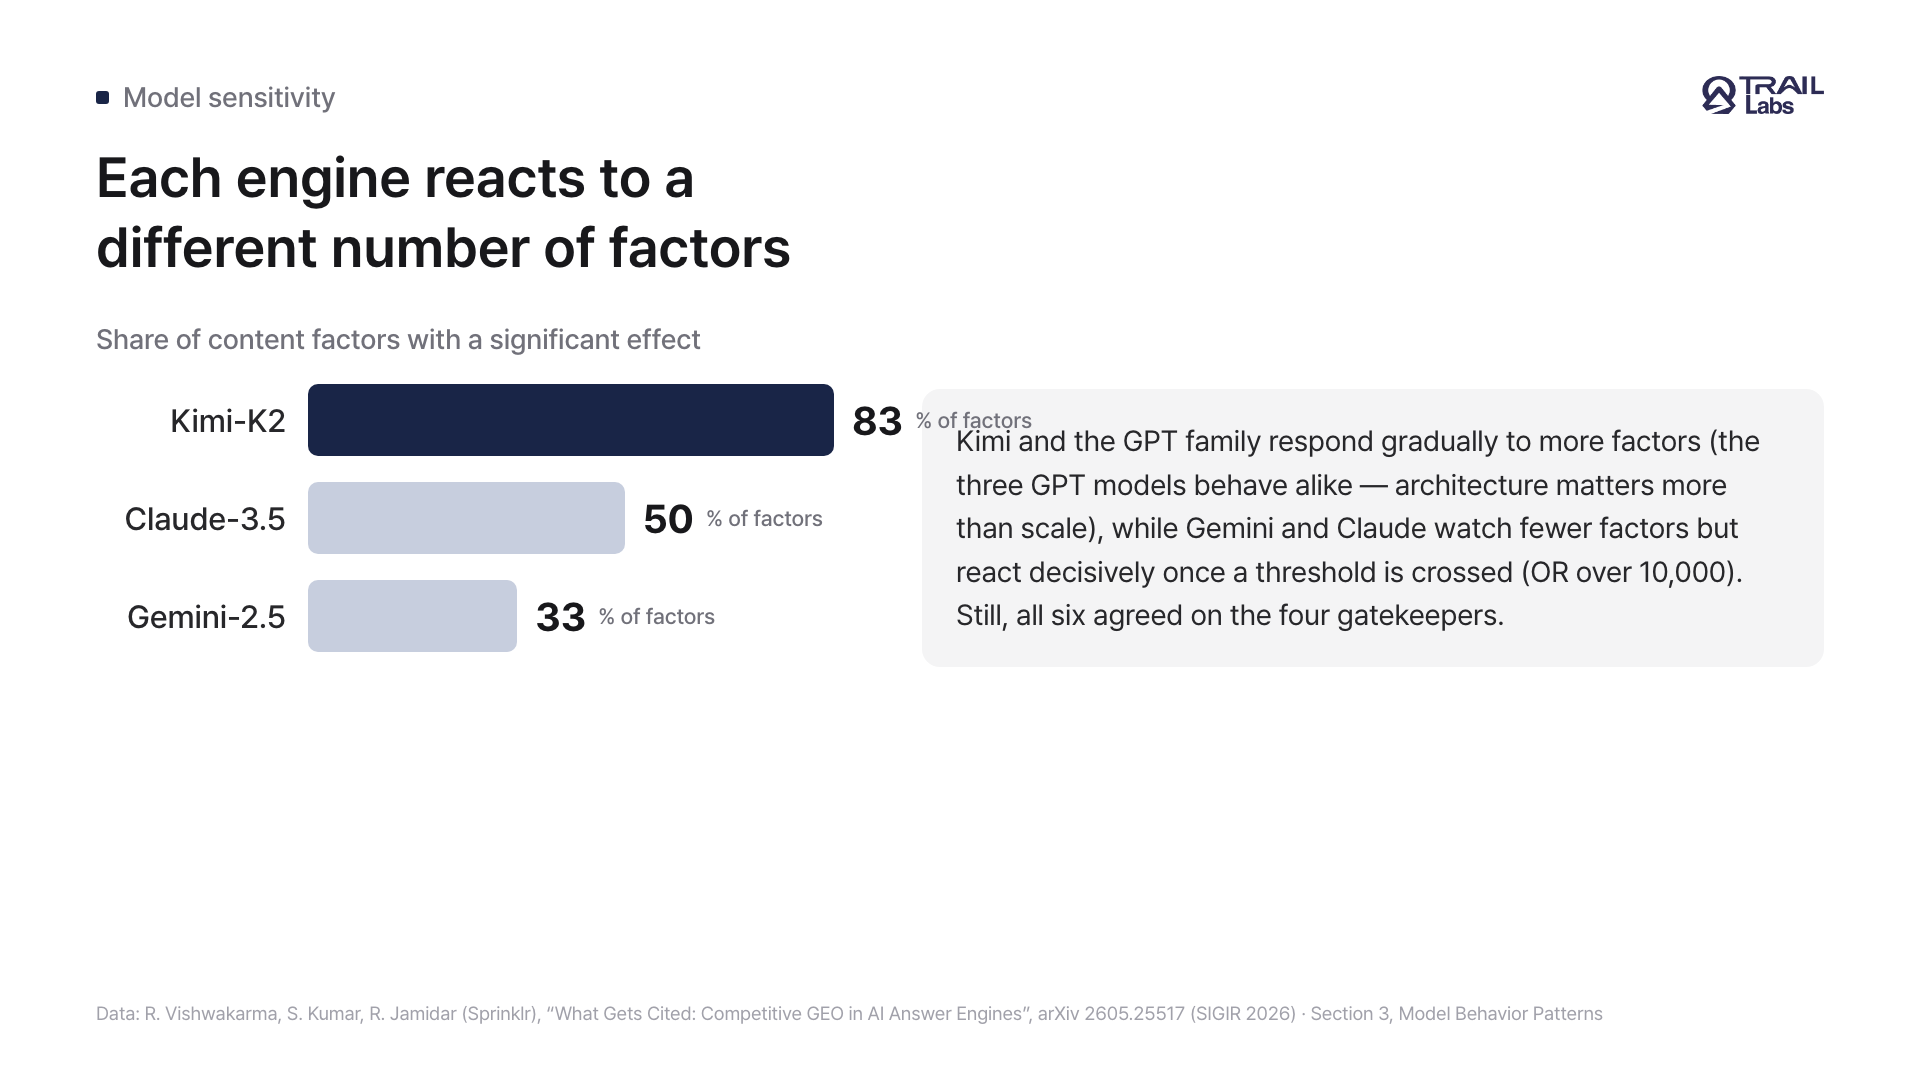
Figure 3. Engines reacted to different numbers of factors.
What are the limits of this study?
The authors state clear limits [1]. First, to isolate one factor they fixed the field to two candidates, while real AI search usually handles five to ten or more pages at once [1]. Second, the content came from 100 product-review blogs across 50 B2C categories, so non-product or non-comparison contexts may not follow [1]. Third, because brands and publishers were fully anonymized, any preference for well-known brands or trusted domains is not present in these results, and the authors leave a follow-up with real brands as future work [1]. Fourth, GPT-4o was used to build the experimental content [1]. So individual numbers are safer read as direction than as precise ratios [1].
How does this connect to TRAIL Search?
This paper's core question meets a place TRAIL Search already works. The product pairs cases where a competitor was cited for a query but your asset was not, and compares them. It scores fit to the query intent, overlap of key terms, completeness, and freshness. The price and timestamp this paper flags as gatekeepers sit inside that completeness and freshness scoring.
What we can push further is the paper's gate framing: treating these four as pass-or-fail rather than weighted points, which is closer to how it describes them. The study's direction, to look at content completeness before formatting, also matches our diagnostic order of finding missing information before polishing style. Structure itself, though, showed a standalone effect in other work (GEO-SFE), so we check structure and completeness together.
You can continue with Why a Page Is Not Cited in AI Search, How to Repair It, When Google AI Overviews appear, what they cite, and Does AI Search Cite AI-Written Content.
Frequently asked questions
What does AI search look at when deciding which page to cite?
In this study, four signals acted first: topic match, a stated price, a recent timestamp, and a front position inside the context. All six models moved the same way, and the authors read these four as necessary conditions, so dropping any one sharply raised the odds of losing the citation to a rival document. Factors like specs and evidence only mattered once these four were met.
What must content have to be cited in AI search?
Meet the four gatekeepers first, then fill the second-tier factors. Spec information and competitor comparisons (completeness), confident tone and evidence (trustworthiness), and ratings or reviews (social proof) decided citations with odds ratios from 2.1 to 243 by the authors' summary, with a few factors larger but on unstable estimates read as direction. A page without a stated price fell behind at gatekeeper scale, so simply stating the price made a large difference.
Does changing paragraph structure improve AI search citations?
In this experiment it barely did. Whether paragraphs were dense or split into sections, and whether information was grouped or scattered, had almost no relation to being cited, because the models read the substance regardless of visual structure. So the authors advise filling in missing information before polishing format.
Do price and date affect AI search citations?
Yes, both acted as gatekeepers. A page without a stated price fell far behind, and a 2026 date beat a 2019 one. One counterintuitive finding is that having no date beat having an old one, though only in some models and weakly, so keeping a date current is the first thing to look at rather than deleting old dates.
References
Summary
- A Sprinklr team pitted two documents that differ in exactly one factor against each other across 6 AI models and 252,000 trials, isolating what decides a citation under controlled conditions.
- Four factors acted as gatekeepers: topic match, stated price, recent timestamp, and front position in context. All six models agreed, and dropping any one sharply raised the odds of losing the citation to a rival (the authors read them as necessary conditions).
- After the gatekeepers, specs, comparisons, confident tone, evidence, and social proof decided citations with odds ratios of 2.1 to 243 by the authors' summary (a few larger but on unstable estimates), while paragraph density and layout were almost irrelevant.
- Engines reacted to different numbers of factors, but across this experiment's six models the four gatekeepers pointed the same way.
- The authors note limits: a controlled 2-document contest, content from B2C product-review blogs, brand and domain trust removed by anonymization, and GPT-4o used to build the corpus.
Check this topic against your own brand
TRAIL Search measures how ChatGPT and Perplexity answer your customers' questions and finds and fixes where the brand is missing, turning this post into a diagnosis. Start with 10 questions, no card required.
More posts
Cutting LLM agent costs: delegate decisions to a 4B model
Cutting LLM agent costs: delegating choices to a small decision model saved 81 to 89 percent, but only with thresholds fitted on the agent's own runs.
How to build a small LLM: Sheared-LLaMA's 3% compute path
How to build a small LLM, what LLM pruning is, whether small models are enough for AI agents, and the cost of building one, read through Sheared-LLaMA.
The world model that teaches a robot from video: V-JEPA 2
Whether you can teach a robot from video alone, what an AI world model is, and how it differs from a video generator, read through Meta's V-JEPA 2 paper.
Keep reading on this topic
- Does AI search use your exact question? 70,000 queries showHow AI search turns a question into queries, why uncited pages are not irrelevant, and what retrievers miss, from Perplexity's Q2D-Web benchmark paper.
- Is agent memory better than RAG over the raw conversation?A 2026 UIUC study of why agent memory systems trail RAG over raw history, what LLM summaries lose, and how a path back to the source cuts the loss.
- Why RAG misses the evidence an answer needsA 2026 MBZUAI study of why RAG retrieves only part of the evidence multi-fact questions need and how chunking erases document identity.
This post is part of the Papers category, which collects all 36 posts on the topic. See all posts in Papers