Calibrating a marketing mix model with geo-experiments
Subtract the treatment region from the control region and the carryover, saturation, and effectiveness parameters come straight out of the experiment. A 2026 structural estimation paper explained
One ROAS number per geo-experiment discards carryover and saturation. A 2026 paper estimates all three MMM parameters from the control-treatment gap.
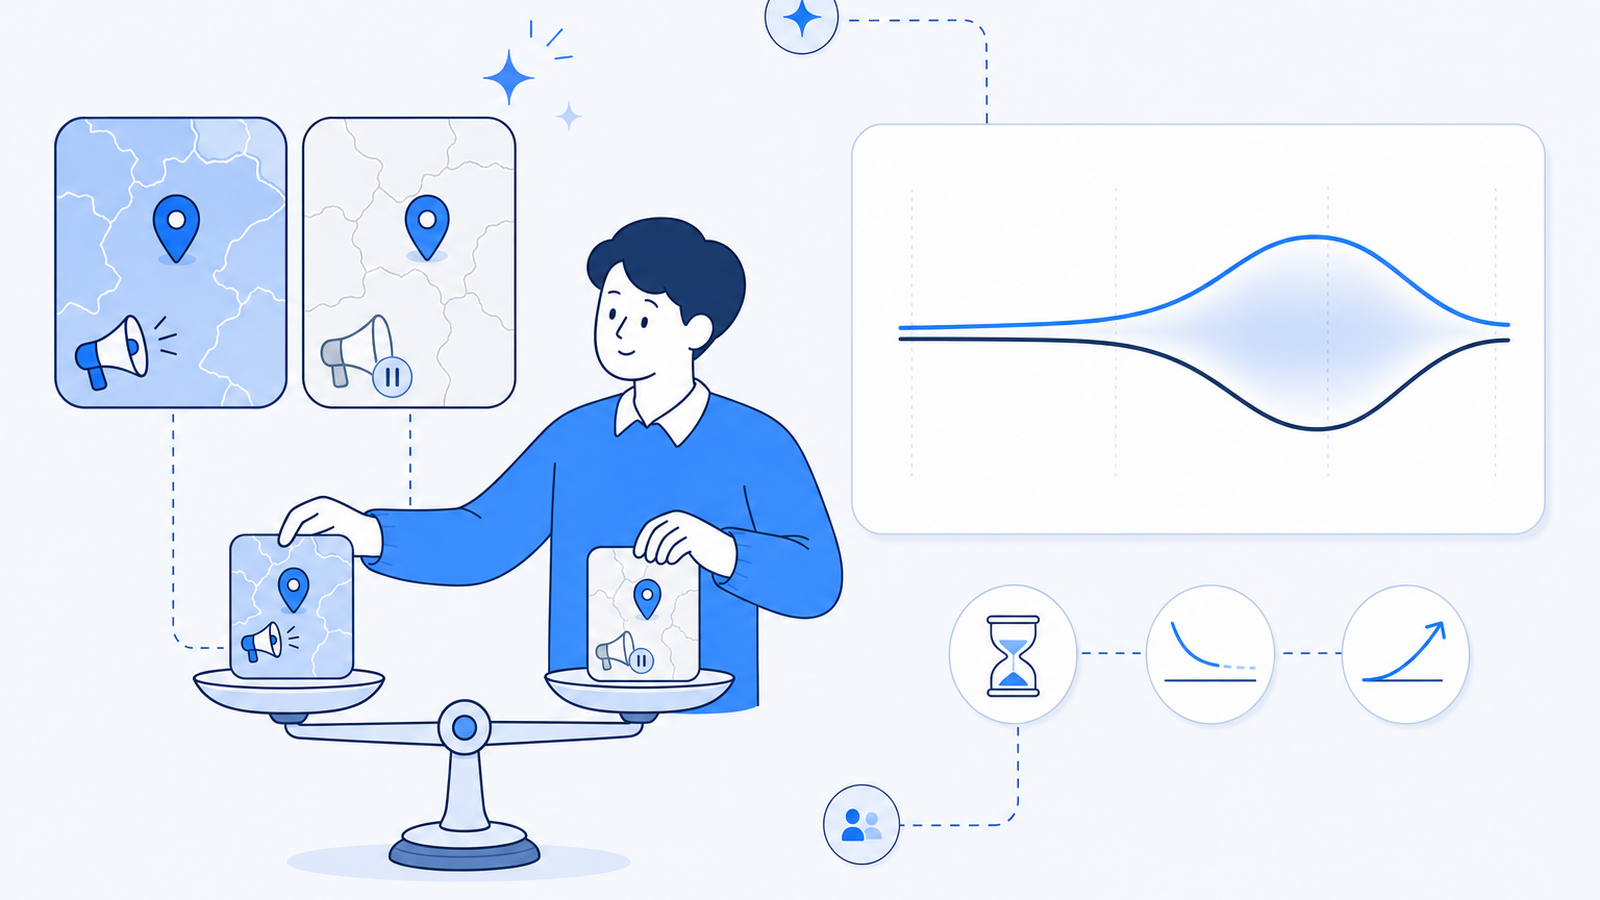
When you calibrate a marketing mix model with geo-experiments, do not reduce each experiment to one ROAS number. Keep the weekly sales difference between control and treatment regions as a time series, and you can estimate carryover, saturation, and effectiveness directly from the experiment. Niklas Heusch proposes this in Structural Estimation of Marketing Mix Model Parameters from Geo-Experiments[1], posted to arXiv in August 2026. On synthetic data the true ROAS was 4.20x, an MMM fitted on observational data estimated 10.66x, and this method with four experiments estimated 4.14x[1]. All of the evidence is synthetic.
This article is based on the arXiv v2 manuscript (12 pages, not yet peer reviewed), read through the appendices, with table values checked against the original[1]. The paper has a single author whose contact address is at Zalando. The data comes from a synthetic benchmark[2] released by the same author.
We build a product that repeatedly measures brand mentions in AI answers, so we have a stake in measurement methodology. We did not run this method ourselves and report the paper's numbers. Our earlier article, Calibrating a marketing mix model with incrementality experiments, covered Google's method of putting experimental ROAS into a prior[3]. This paper is about the information that method discards.
Why does an MMM overestimate ROAS?
Ad budgets are not assigned at random. They follow demand, so a marketing mix model (MMM) fitted only on observational data reads that correlation as an advertising effect[1]. Firms raise budgets when they expect sales to rise, and automated bidding raises spend in weeks when conversions come easily. The model cannot tell whether sales rose because of advertising or advertising rose because sales were expected to.
For an MMM to return causal effects, the error term must be independent of spend once the controls are conditioned on[1]. That means observing every factor that moves both budget and sales: expected demand, competitor actions, word of mouth. A comparison against large field experiments at Facebook also reported that observational methods fail to recover the results of randomized experiments[5].
A geo-experiment cuts this link with random assignment. The market is split into geographic units, the units are randomly assigned to treatment or control, and advertising is changed in the treatment group during the test. A common design switches treatment-group advertising off entirely[1].
What is lost when a geo-experiment becomes one ROAS number?
Summarizing an experiment as one ROAS number removes all the variation over time that reveals carryover (adstock) and saturation[1]. Standard practice divides the summed sales difference over the test period by the summed spend difference.
Here is sales in week and is ad spend in that week. The value gives the average return. It says nothing about how many weeks an effect lasts or how fast it shrinks as spend grows.
Both signals are present in the experimental time series[1]. When ads are switched off, the sales gap does not open at once. It opens at the rate the treatment group's adstock runs down, and it closes at the same rate when ads resume. That transition speed sets the carryover decay rate. Comparing experiments at different spend levels shows how far short of double the gap falls when spend doubles, which is the shape of the saturation curve.
The three existing calibration methods all reduce the experiment to an aggregate statistic[1].
| Method | How the experiment enters | What it identifies | What it misses |
|---|---|---|---|
| Google Meridian | ROAS as a model parameter, experiment as its prior[3] | Level of effect | Experiments at different spend levels, carryover, saturation |
| Meta Robyn | Deviation from experimental lift as a third objective | A constraint on total effect | Separating carryover from saturation |
| PyMC-Marketing | Lift observations added to the likelihood as points on the saturation curve[6] | Saturation | Carryover |
| Differenced structural estimation | Weekly differenced time series as the likelihood | Carryover, saturation, effectiveness | The curve outside the tested range |
Table 1. Four ways to calibrate an MMM with experiments. Source: the discussion in Heusch 2026, Section 6.B[1], arranged as a table.
The differencing equation: what remains after subtracting treatment from control?
Subtracting treatment-group sales from control-group sales leaves only the tested channel's three parameters and observed spend[1]. The paper treats the two groups as parallel universes that differ only in advertising on the tested channel. Sales in each group are a common term plus the channel effect.
holds baseline demand, the contribution of other channels, pricing and promotions, seasonality, and every unobserved factor. Random assignment makes this term the same in both groups, so it cancels.
Here is adstocked spend, is the saturation function, and is the difference between the two groups' errors. Adstock is a weighted average of the last weeks of spend, and saturation is a logistic function.
- : carryover decay rate. At 0 only this week's spend matters. The larger it is, the longer past spend lingers.
- : saturation speed. The larger it is, the lower the spend at which diminishing returns set in.
- : effectiveness. It converts saturated adstock into incremental revenue.
There is no need to assume the controls capture every confounder, and no need to model how budgets are set[1]. Identification comes from the experimental design.
Estimation: reshape to wide format, stack experiments, fit with Bayesian inference
The key data step is reshaping to wide format so that each row is a complete observation of one week[1]. A row holds that week's sales difference plus this week's and the previous weeks' spend for both groups. Rows no longer depend on each other in time, so rows from a January test and a June test can simply be stacked.
[Geo-experiment series]        [Wide format]                    [Estimation]
 weekly sales, both groups  ->  one row = sales difference    ->  likelihood of the
 weekly spend, both groups      + spend for both groups           differencing equation
        |                         (current + lags)                posteriors of a, l, b
 pre-test, test, cooldown         stack several experiments       ROAS and response curve
A geo-experiment is smaller than the national market, so the data is put on the MMM's scale. If the treatment group is 40% of the country, its sales and spend are divided by 0.4 to express them at national scale, and whatever transformation the MMM uses (such as dividing by the maximum) is applied in the same way[1].
The priors are the defaults of PyMC-Marketing v0.19[1]. PyMC-Marketing's existing way of adding experiments is described in its lift test calibration notebook[6]. The observational MMM used as a benchmark has the same priors on its media parameters, so the gap between the two methods cannot come from prior choice.
| Parameter | Prior | Rationale |
|---|---|---|
| Beta(1, 3) | Limited carryover for digital channels | |
| Gamma(3, 1) | Positive, mode at 2 | |
| HalfNormal(2) | Positive effectiveness | |
| HalfNormal(0.5) | Observation noise |
Table 2. Priors of the structural estimation model. Source: Heusch 2026, Table 1[1].
Estimation runs PyMC's NUTS sampler with 4 chains and finishes in under 30 seconds on a laptop[1].
Synthetic data results: true ROAS 4.20x, MMM 10.66x, structural estimation 4.14x
The MMM fitted on observational data overestimated ROAS by a factor of about 2.5, while the structural model fitted on experimental time series kept the truth inside its 90% interval[1]. The synthetic data covers 156 weeks of an online retailer with three channels: paid search, social, and TV. Budgets respond to expected demand and a bidding algorithm chases performance, so spend is endogenous[2].
Four experiments were run on the paid search channel. Each has 4 pre-test weeks, 4 test weeks with treatment spend at zero, and 8 cooldown weeks, and all 16 weeks enter the estimation. Mean weekly control-group spend differed across tests at EUR 54K, 129K, 64K, and 57K, and together the four tests cover adstocked spend from roughly EUR 43K to 194K per week[1].
| Method | ROAS | 90% interval | Covers truth |
|---|---|---|---|
| Truth | 4.20x | n/a | n/a |
| MMM (realistic) | 10.66x | 6.99–14.42 | No |
| MMM (oracle controls) | 8.45x | 6.97–9.82 | No |
| Structural (2 tests) | 4.31x | 3.87–4.74 | Yes |
| Structural (4 tests) | 4.14x | 3.77–4.51 | Yes |
Table 3. ROAS estimates for the paid search channel. The realistic specification controls for a promotion dummy, promotional price level, and three annual Fourier harmonics. Source: Heusch 2026, Table 2[1].
The second row is the most striking result in the paper. A model given every true confounder from the data-generating process (true promotion state, price level, seasonal component, product-quality drift, market sentiment) still estimated 8.45x[1]. Even with variables no practitioner could have, close to half of the bias remained. The author gives two causes. The bidding algorithm reacts to each week's random performance swings, which no covariate can absorb, and the true baseline combines its components multiplicatively while the controls enter linearly.
The gap also shows at the parameter level.
| Method | (carryover) | (saturation) | (effectiveness) |
|---|---|---|---|
| Truth | 0.20 | 1.71 | 0.18 |
| Structural (2 tests) | 0.18 [0.08, 0.29] | 2.28 [0.91, 3.48] | 0.17 [0.11, 0.32] |
| Structural (4 tests) | 0.19 [0.09, 0.28] | 1.94 [0.65, 3.10] | 0.20 [0.11, 0.44] |
| MMM (realistic) | 0.50 [0.37, 0.62] | 1.27 [0.38, 2.62] | 0.86 [0.30, 2.03] |
Table 4. Parameter estimates. Brackets are 90% credible intervals, and and are on the estimation scale (spend and sales each divided by their maximum). Source: Heusch 2026, Table 3[1].
The observational MMM estimated carryover at 0.50 against a true 0.20, and effectiveness at several times the truth[1]. Structural estimation put carryover almost exactly on the truth, but its intervals for and are wide. Why a channel effect should not be read as a single number is covered in credible intervals in Bayesian MMM.
Saturation and effectiveness are not identified separately: read the response curve
and move together with a posterior correlation of −0.68, and what the data pins down tightly is the response curve the pair produces[1]. A flat curve with a large coefficient and a steep curve with a small coefficient give nearly the same response over the spend range the experiments covered. That is why the ROAS interval is narrow while the interval for each parameter is wide.
Within the spend range the experiments covered, the posterior response curves sit on top of the true curve. Outside it they fan out[1]. A recommendation to raise the budget far above the tested range is not supported by the experiments and rests on the assumed shape of the saturation function. Dew and coauthors also point out that saturation and time-varying effectiveness cannot be told apart in observational data[4].
Changing the priors barely moved the result. The structural ROAS was 4.07x under diffuse priors and 4.14x under informative priors, a shift of under 2% in the point estimate[1]. The observational MMM kept its bias under alternative priors at 11.67x. The overestimate comes from endogeneity in the data more than from the choice of prior.
Limitations
Every result in this paper comes from synthetic data built by the author, and there is no application to a real company's experiments[1]. The limitations the author states, or that can be confirmed in the manuscript, are these.
- The functional forms that generate the data (geometric adstock, logistic saturation) are the same as those in the estimation model. Performance under a misspecified model was not tested.
- Only one channel (paid search) with short carryover () was tested. There are no results for a long-carryover channel such as TV.
- The method assumes no spillover between regions. If control-region advertising reaches treatment-region consumers, the effect is underestimated.
- Parameters are assumed constant across experimental periods. If creative fatigue or competition changes, the estimate is closer to an average.
- The design requirements are higher than standard. A two-week test may be too short to identify carryover, and identifying saturation needs several experiments at different spend levels.
- Ways to combine the estimates with a full multi-channel MMM (passing a prior, a joint likelihood, two-stage estimation) are proposed but not tested.
- The manuscript is not peer reviewed and has a single author.
What TRAIL takes from this
The same problem appears in GEO measurement. Brands fix the products and pages where they expect demand first. When mentions of a fixed page rise, a before-and-after comparison cannot tell whether the fix caused it or the topic was already gaining interest. A framework for turning AI answer exposure into an MMM input is covered in measuring GEO's revenue impact.
TRAIL Search asks a set of questions to the engines selected in your plan on a schedule, and records mentions, rank, and cited URLs by engine, question, and time of check. Revenue and ad spend are outside what we measure, so our numbers alone cannot state a ROAS. We take three measurement design rules from this paper.
- A time series over a single summary value. How the mention rate changed over the days after a fix carries information about persistence, and one before-and-after average removes it.
- The difference against a comparison group. Measuring pages or question groups that were not changed over the same period, and subtracting them, cancels engine updates and seasonal shifts. Design criteria are in how to design an AI search exposure experiment.
- Claims only within the tested range. Stretching an effect confirmed on 20 questions to 2,000 questions is the same kind of claim as the out-of-range extrapolation in this paper.
The author states that the notebooks and data are public[1][2]. To run it yourself, start from the data generator in the synthetic benchmark paper.
Frequently asked questions
What is wrong with how geo-experiment results go into an MMM today?
Each experiment is reduced to a single ROAS number. Dividing total incremental revenue by total incremental spend keeps the average return, but it drops how the sales gap opened and closed over the weeks after ads were switched off (carryover) and how the gap differed between experiments run at different spend levels (saturation). This paper keeps the weekly time series and estimates all three parameters together.
Why does an MMM overestimate ROAS?
Because ad budgets are not assigned at random. Firms raise budgets when they expect high demand, and automated bidding raises spend in weeks when performance is good. A model that only sees observational data reads that correlation as an advertising effect. In the paper's synthetic data the true ROAS was 4.20x and a practitioner-style MMM estimated 10.66x.
Do more control variables fix it?
Not in this paper's experiment. A model given every true confounder from the data-generating process still estimated 8.45x, and its 90% interval excluded the truth. The bidding algorithm reacts to each week's random performance swings, so a correlation remains that no covariate can absorb.
How should experiments be designed to use this method?
Identifying carryover needs the transition weeks after ads are switched off and back on, so a two-week test may be too short. Identifying saturation needs several experiments at different spend levels. The paper used four experiments, each with 4 pre-test weeks, 4 test weeks, and 8 cooldown weeks.
References
- [1]Niklas Heusch, "Structural Estimation of Marketing Mix Model Parameters from Geo-Experiments", arXiv:2608.21128 v2 (2026-09)
- [2]Niklas Heusch, "A Synthetic Benchmark Dataset with Endogenous Marketing Spend for Validating Marketing Mix Models", arXiv:2608.21130 (2026-08)
- [3]Yingxiang Zhang, Mike Wurm, Eddie Li, Alexander Wakim, Joseph Kelly, Brenda Price, Ying Liu, "Media Mix Model Calibration With Bayesian Priors", Google (2024-01)
- [4]Ryan Dew, Nicolas Padilla, Anya Shchetkina, "Your MMM is Broken: Identification of Nonlinear and Time-varying Effects in Marketing Mix Models", arXiv:2408.07678 (2024-08)
- [5]Brett R. Gordon, Florian Zettelmeyer, Neha Bhargava, Dan Chapsky, "A Comparison of Approaches to Advertising Measurement: Evidence from Big Field Experiments at Facebook", Marketing Science 38(2) (2019)
- [6]Juan Camilo Orduz, "Lift Test Calibration", PyMC-Marketing documentation (2024)
Summary
- Ad budgets follow demand, so an MMM fitted on observational data reads correlation as effect. On synthetic data it estimated a true ROAS of 4.20x as 10.66x.
- A model given every true confounder still estimated 8.45x. Adding controls did not repair it.
- Subtracting treatment-region sales from control-region sales removes seasonality, other channels, and unobserved demand, leaving only carryover, saturation, and effectiveness.
- Structural estimation on four pooled experiments gave 4.14x (90% interval 3.77 to 4.51), covering the truth. The evidence is synthetic, and the response curve is not identified outside the spend range the experiments covered.
Check this topic against your own brand
TRAIL Search measures how ChatGPT and Perplexity answer your customers' questions and finds and fixes where the brand is missing, turning this post into a diagnosis. Start with 10 questions, no card required.
More posts
Solving LLM recommender cold start with knowledge graph RAG
A KDD 2026 study let an LLM recommender pick knowledge graph retrieval depth per query. Cold-start accuracy rose from 0.39 to 0.50 and latency halved.
RAG answers improve more from verification than retrieval
Across 16 combinations of four RAG features, a post-generation completeness check alone beat three retrieval features combined, at double the latency.
AI agents already know when to search the web
LLM agents know whether they need a tool like web search before answering (AUROC 0.89 to 0.96). A UCSD study used that signal to cut tool calls by 48%.
Keep reading on this topic
- AI Overviews cite different sources than Google searchGoogle Search, AI Overviews, and Gemini cite sources overlapping only 18%, and sites blocking the AI crawler get dropped. A SIGIR 2026 study of 11,500 queries.
- AI search knows your product but rarely recommends itAI recognizes a product 99% by name but surfaces it only 3% in discovery queries. A 2025 study of 112 startups found GEO scores did not predict it.
- Measuring GEO's revenue impact with a marketing mix modelTo measure GEO's revenue effect, turn how often AI answers name a brand into expected exposures per market, then feed it to an MMM. A 2026 paper explained.
This post is part of the Papers category, which collects all 44 posts on the topic. See all posts in Papers